AI cloud on
our own metal
We build and operate the data centers behind this API. OpenAI-compatible inference on hardware we rack and tune ourselves, priced per token in prepaid credits. GPUs by the hour follow as the fleet comes online.
Two ways onto our hardware
Serverless Inference
Open models behind Chat Completions, Responses, and Anthropic Messages, plus a streaming chat UI. Per-token pricing in credits, published on every model. Streams over SSE.
Browse models and pricesGPU Cloud
Dedicated GPUs by the hour for training, fine-tuning, and self-managed inference, on machines we rack ourselves. The fleet is in commissioning now.
See hardware and join the waitlistLive catalog, live prices
The same table billing reads from. 1 credit = $0.01, deducted per token.
| Model | Context | Input / 1M tokens | Output / 1M tokens |
|---|---|---|---|
| Qwen3 Coder 30B A3Bchat-default | 64K | 10 cr ($0.10) | 30 cr ($0.30) |
| Qwen 3.6qwen3.6 | 256K | 40 cr ($0.40) | 120 cr ($1.20) |
We run the racks
Most AI APIs are a margin on someone else's cloud. Ours is the cloud.
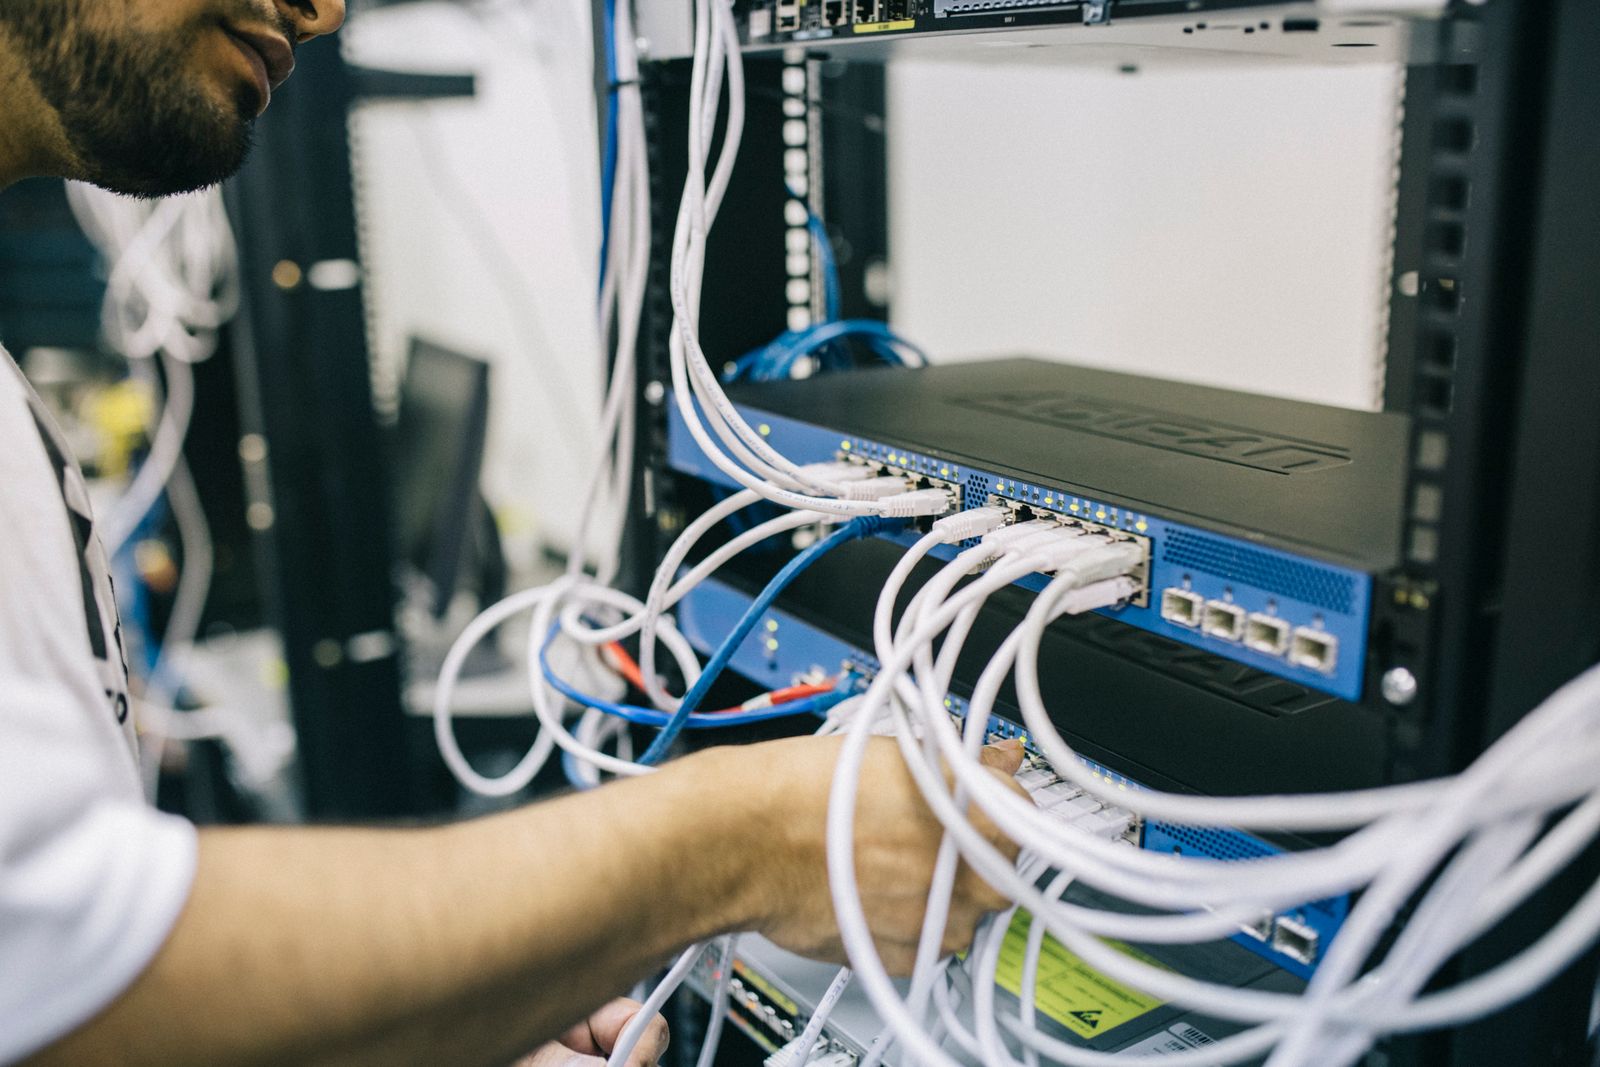 hands on the metal
Our racks, our rules
Inference runs in our own data centers, on machines we bought, racked, and tuned ourselves. Nobody sits between you and the hardware.
Isolation in the database
Tenant separation is row-level security in Postgres. The database enforces it on every query, beneath any application code.
Honest capacity
The admission queue is sized to measured throughput. Under load you see your position in the queue or an explicit timeout. Quality never degrades silently.
Published numbers
Benchmarks come from real runs on the machines that serve you. Every model card prices input and output per 1M tokens, to the credit.
Served from data centers we own and operate. The GPU Cloud page shows what is coming next.
From signup to first token in minutes
Create an account
You start with 100 free credits and no card. Your account is an organization from day one.
Get a key or open chat
Generate an API key and point your editor at the contract on the docs page. The streaming chat workspace is ready the same minute.
Pay per token
Credits are deducted at the model's published rate. Top up in fixed packages, and every movement lands in a ledger you can read.
Prepaid credits, plain prices
1 credit is one cent. Credits never expire, and there is no subscription.
Common questions
hakk.ai is an infrastructure operator. We own data centers and the machines in them, and inference runs on that hardware directly. The fleet is growing, with more machines in commissioning.
Put your tokens on our metal.
We onboard in small batches and set up every account personally. Request access and start with 100 free credits.